ViewTube

ViewTube
Sign inSign upSubscriptions
Filters

Upload date

Type

Duration

Sort by

Features

Reset

448 results

Deep Dives on Apache Spark and GrowDataSkills
Apache Spark In 15 Minutes | What Is Apache Spark ? For Data & AI Engineering

10:18 – How Apache Spark fits in Data Engineering 11:49 – How Uber migrated from Hive to Spark SQL 12:08 – How Apache ...

18:25
Apache Spark In 15 Minutes | What Is Apache Spark ? For Data & AI Engineering

6,570 views

3d ago

Tech in Layers
Photon on Databricks | The C++ Vectorized Engine, Fallback to Spark and the Cost Trade-Off

"What is Photon, and when does it help?" has a crisp answer, and most candidates only get half of it. This video draws Photon as ...

2:40
Photon on Databricks | The C++ Vectorized Engine, Fallback to Spark and the Cost Trade-Off

3 views

12h ago

Dataverse Hub
Amazon Data Engineer Interview Experience | Real Questions & Detailed Discussion | SQL, PySpark, AWS

What does an Amazon Data Engineer interview actually look like? In this session, Aviral Shukla, Data Engineer at Deloitte, shares ...

49:37
Amazon Data Engineer Interview Experience | Real Questions & Detailed Discussion | SQL, PySpark, AWS

4,570 views

3d ago

Data with Pranjal
I Analyzed 100 Data Engineer Jobs. Here’s What Companies Want

Stop getting overwhelmed by endless tools on your data engineering roadmap. Learn the core pillars that actually matter for your ...

8:55
I Analyzed 100 Data Engineer Jobs. Here’s What Companies Want

16,429 views

2d ago

RADACAD
Fabric Data Warehouse Deep Dive, Polaris & GPU | Fabric Insider Ep. 21 | Joanna Podgoetsky

From Polaris, the distributed query engine, to GPU-accelerated queries, configurable retention, and data clustering, Fabric Data ...

42:03
Fabric Data Warehouse Deep Dive, Polaris & GPU | Fabric Insider Ep. 21 | Joanna Podgoetsky

915 views

1d ago

Edukast AI
Data Transformation Explained: ETL vs ELT, dbt, Spark, Flink | Data Engineering Ep 4

Raw data can't answer questions by itself. Episode 4 of the Data Engineering series is stage three of a data pipeline: compute, ...

3:22
Data Transformation Explained: ETL vs ELT, dbt, Spark, Flink | Data Engineering Ep 4

17 views

6d ago

Pista Academy
Data Engineering & Big Data Specialist: SQL, NoSQL, Hadoop, Spark & Kubernetes - Episode 2

Complete Data Engineering & Big Data Specialist Course | SQL, NoSQL, Hadoop, Spark & Kubernetes Welcome to the complete ...

16:15
Data Engineering & Big Data Specialist: SQL, NoSQL, Hadoop, Spark & Kubernetes - Episode 2

181 views

2d ago

Sawan agarwal
🚀 Lecture 25: Advanced Parquet in PySpark | Schema Merging, Nested Data & Multiple Folders

Welcome to Lecture 25 of our PySpark learning series! In this lecture, we move into Advanced Parquet concepts in PySpark ...

5:21
🚀 Lecture 25: Advanced Parquet in PySpark | Schema Merging, Nested Data & Multiple Folders

52 views

5d ago

DATA ACE
Broadcast Join vs Shuffle Join in Databricks | Episode 14

Which is faster in Databricks: a broadcast join or a shuffle join? In this two-minute data-engineering lesson, you'll learn how both ...

2:17
Broadcast Join vs Shuffle Join in Databricks | Episode 14

7 views

6d ago

CLOUD FREAK TECHNOLOGY
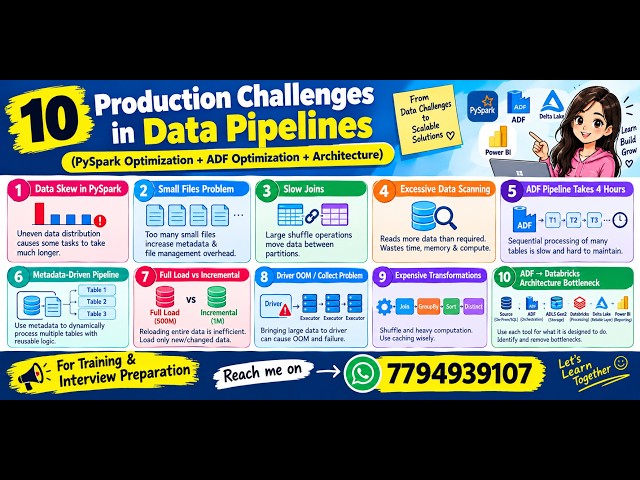
10 Production Challenges in Data Pipelines #azuredataengineering #pyspark #dataengineering #sql

Data Skew: Data skew occurs when data is unevenly distributed across Spark partitions, causing some tasks to take much longer ...

4:44
10 Production Challenges in Data Pipelines #azuredataengineering #pyspark #dataengineering #sql

100 views

4d ago

vlogommentary
How to Convert and Explode a String of Key-Value Pairs into Separate Columns in PySpark

Avoids UDFs: Keeps it within Spark SQL functions, ensuring better optimization and performance. Flexible: Easily adapts to similar ...

2:51
How to Convert and Explode a String of Key-Value Pairs into Separate Columns in PySpark

3 views

5d ago

Pista Academy
Data Engineering & Big Data Specialist: SQL, NoSQL, Hadoop, Spark & Kubernetes - Episode 1

Complete Data Engineering & Big Data Specialist Course | SQL, NoSQL, Hadoop, Spark & Kubernetes Welcome to the complete ...

19:51
Data Engineering & Big Data Specialist: SQL, NoSQL, Hadoop, Spark & Kubernetes - Episode 1

100 views

2d ago

The Data and AI Guy
What is Trino? Trino Explained for Beginners!

One SQL statement that joins a Postgres table to a folder of Parquet files in object storage, with no pipeline, no copy, and no ...

11:08
What is Trino? Trino Explained for Beginners!

1,260 views

4d ago

Shubham Kandpal
Client mode vs Cluster mode in spark #databricks #pyspark #python

Apache spark / Pyspark from scratch 5. Sql & Spark SQL - Interview ready 6. Databricks & Delta Lake - The Industry ready ...

6:15
Client mode vs Cluster mode in spark #databricks #pyspark #python

25 views

1d ago

ElevateMyCode
PySpark DataFrame Functions |  With Examples | PySpark Tutorial for Beginners

... data apache spark tutorial spark sql pyspark select pyspark filter pyspark withcolumn pyspark groupby pyspark join pyspark sort ...

9:15
PySpark DataFrame Functions | With Examples | PySpark Tutorial for Beginners

221 views

5d ago

PathNex - Shaping Careers
BigQuery & Managed Apache Spark Explained | GCP Interview Concepts| Data Engineering

Welcome to the Data Engineering Course 🚀 In this session, we cover two of the most important GCP services used in modern Data ...

35:23
BigQuery & Managed Apache Spark Explained | GCP Interview Concepts| Data Engineering

475 views

Streamed 4d ago

Show more