Upload date
All time
Last hour
Today
This week
This month
This year
Type
All
Video
Channel
Playlist
Movie
Duration
Short (< 4 minutes)
Medium (4-20 minutes)
Long (> 20 minutes)
Sort by
Relevance
Rating
View count
Features
HD
Subtitles/CC
Creative Commons
3D
Live
4K
360°
VR180
HDR
18,783 results
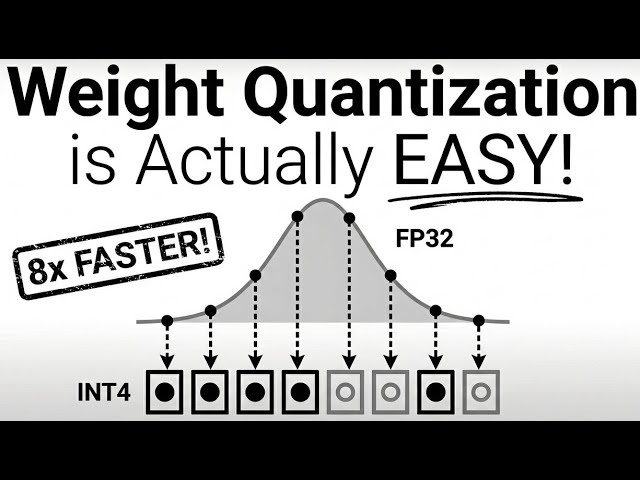
In this video we define the basics of quantization and look at how its benefits and how it affects large language models.
42,003 views
2y ago
LLM quantization is how a 70B model that needs 140GB of memory gets small enough to run on a normal GPU. Every model you ...
22,961 views
2mo ago
In this video, we discuss the fundamentals of model quantization, the technique that allows us to run inference on massive LLMs ...
81,982 views
1y ago
Text:* https://github.com/The-Pocket/PocketFlow-Tutorial-Video-Generator/blob/main/docs/llm/quantization.md 0:00:00 ...
13,691 views
10mo ago
Run massive AI models on your laptop! Learn the secrets of LLM quantization and how q2, q4, and q8 settings in Ollama can save ...
551,137 views
Need some help with a project or some consulting? Contact me here: https://www.neuralnine.com/services The Python Bible ...
9,190 views
6mo ago
00:00 Introduction to LLM Quantization 02:15 What is Quantization? 04:45 Post-Training Quantization (PTQ) vs. QAT 07:30 GPTQ ...
4,900 views
7mo ago
Welcome back to the Ollama course! In this lesson, we dive into the fascinating world of AI model quantization. Using variations of ...
34,537 views
Every time I do a video about a model I get a comment saying "Well you never said what it takes to run it!" Well since I am not ...
15,502 views
Quantization is an excellent technique to compress Large Language Models (LLM) and accelerate their inference. In this video ...
25,186 views
Q8 vs Q6 vs Q5 vs Q4 vs Q3 vs Q2: how much quality does LLM quantization really cost? Measured on Qwen 3.8 27B GGUF, plus ...
15,566 views
3w ago
Quantizing models for maximum efficiency gains! Resources: Model Quantized: ...
30,536 views
This video explores DeepSeek R1, how distilled versions and quantization make it more accessible, and the trade-offs between ...
31,070 views
Ready to become a certified watsonx AI Assistant Engineer? Register now and use code IBMTechYT20 for 20% off of your exam ...
32,900 views
I quantized one model 8 ways to find the exact level it starts making things up. Take your personal data back with Incogni!
134,369 views
4mo ago
QLoRA is the first approach that allows the TRAINING of Large Language Models (LLMs) on a single GPU. It does this by using ...
27,220 views
Learn more about LLM inference here → https://ibm.biz/~Ewjm0UejN Why do LLMs crawl when traffic spikes? Legare Kerrison ...
217,658 views
3mo ago
Try Voice Writer - speak your thoughts and let AI handle the grammar: https://voicewriter.io Four techniques to optimize the speed ...
73,673 views
3y ago
Download Tanka today https://www.tanka.ai and enjoy 3 months of free Premium! You can also get $20 / team for each referrals ...
398,976 views