Upload date
All time
Last hour
Today
This week
This month
This year
Type
All
Video
Channel
Playlist
Movie
Duration
Short (< 4 minutes)
Medium (4-20 minutes)
Long (> 20 minutes)
Sort by
Relevance
Rating
View count
Features
HD
Subtitles/CC
Creative Commons
3D
Live
4K
360°
VR180
HDR
5,592 results
Thanks to Micro Center for sponsoring this video! Check them out below: Shop Build. Upgrade. Save.
273,170 views
2 days ago
Can EXL3 shrink a local model without sacrificing the quality that makes it worth running? Level up your agents with Agent ...
16,149 views
6 days ago
Quantization can make an LLM smaller, faster, and cheaper to run, but the tradeoff is more subtle than a single benchmark score.
3 views
2 hours ago
You will know which quantization level to pick for your card and your task, and which kinds of work break before the file size does.
1 view
Code: https://github.com/louislhotte/Manim-animation How can a large neural network become several times smaller without ...
39 views
4 days ago
Real-world RTX 5090 LLM inference benchmarks: quantization requirements for 70B models, tokens/sec on 32GB, Ollama/vLLM ...
10 views
Are pre-quantized 4-bit LLM checkpoints safe to deploy in production? We briefly talk through quantization verification challenge, ...
29 views
bonsai2 #prismml #localai Bonsai 2 promises something that recently sounded impossible: a free 27B coding model that runs ...
30 views
21 hours ago
How do you fit a 27-Billion parameter frontier reasoning model onto a 12GB or 24GB consumer laptop? In standard BF16 ...
4,097 views
7 days ago
LLM quantization explained: how INT8, INT4, FP8, and NVFP4 shrink massive language models so they actually fit on real ...
9 views
19 hours ago
he weights changed. The file got smaller. The answer was still Paris. How can a 4-bit AI model still work? Follow one real weight ...
18 views
1 day ago
How can a 70-billion-parameter LLM go from roughly 140 GB of raw weights to just 35 GB? The answer is quantization and the ...
99 views
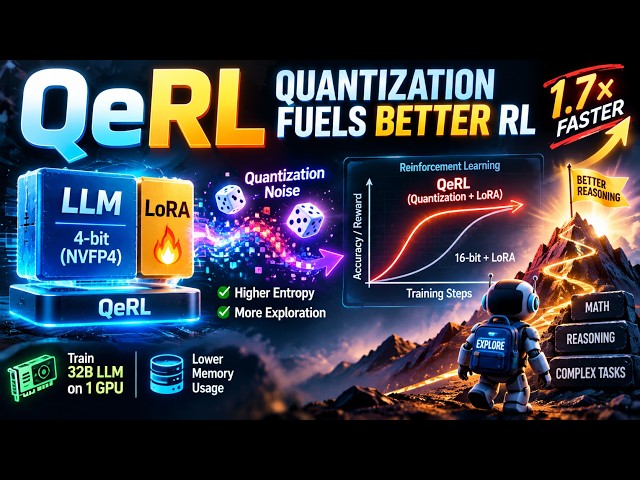
QeRL is a framework that integrates NVFP4 quantization with Low-Rank Adaptation (LoRA) to streamline the reinforcement ...
4 views
Whether you are working with live drums, acoustic guitars, or vocals, getting your tracks perfectly locked to the grid doesn't have to ...
63 views
GGUF quantization just changed with smarter per-tensor bit allocation. Two equally sized GGUF models may no longer preserve ...
11 views
6 hours ago
In this Quick-Tip, I demonstrate a method to getting your Loops & Samples cycling in time to your Sequencer's Tempo using a ...
556 views
What is a Vector-Quantized VAE? A vector-quantized VAE learns a discrete latent space by snapping each encoder output to its ...
5 days ago
LLM quantization explained: why running a large language model at 4-bit can silently break its math, code, and reasoning — even ...
8 views
Retrieval that worked on a laptop gets quietly worse on the real corpus, and the index is almost always why. This video walks the ...
2 views
13 hours ago
Ternary Bonsai 2-27B compresses Qwen 3.8 27B's language backbone to roughly 1.7 bits per weight, producing a model file of ...
108,891 views
3 days ago
Show more