Upload date
All time
Last hour
Today
This week
This month
This year
Type
All
Video
Channel
Playlist
Movie
Duration
Short (< 4 minutes)
Medium (4-20 minutes)
Long (> 20 minutes)
Sort by
Relevance
Rating
View count
Features
HD
Subtitles/CC
Creative Commons
3D
Live
4K
360°
VR180
HDR
9,984 results
llama.cpp's new MoE expert cache took a 125B model from 9.7 to 37.2 tokens a second on one 24 GB GPU. Here's where that 4× ...
52,073 views
2d ago
The same Radeon GPU, the same Qwen model, no new quantization trick: 9.7 tokens per second became 37.2. llama.cpp already ...
15,458 views
3d ago
Install llama.cpp on Windows from the official GitHub release and run GGUF models on your own computer: a chat in the terminal, ...
847 views
6d ago
Last time, PolyStrata made my used $300 Radeon RX 6700 XT 12GB fast. So do you even need it, or is plain llama.cpp good ...
167 views
Meet Llama: run AI models locally on your Mac, right from the menu bar. Find models that fit your Mac, download with one click, ...
4,714 views
1d ago
Underdog Saluki 27B is a new 7.9GB local AI model that compresses the original 55.6GB Qwen 27B model using aggressive 2-bit ...
25,038 views
18h ago
Build an AI Cluster with Android Phones Using llama.cpp Can you turn Android phones into an AI computing cluster?
151 views
4d ago
48GB VRAM for local AI: we ranked ten ways to get 48 gigabytes of graphics memory, cheapest first, at this week's prices, from two ...
6,442 views
14h ago
llama.cpp's built-in server can now speak and listen: a new /tts address turns text into a WAV voice, and a new /v1/realtime ...
17 views
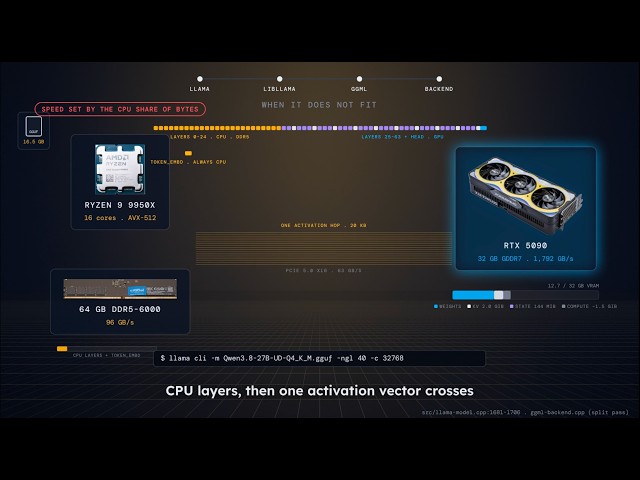
lama.cpp internals explained, step by step. We follow one prompt through the real source code: from the GGUF file, through RAM ...
47 views
8h ago
In this video, I look at an interesting model from Recursive AI called Flint, which is their first public attempt at building a very fast ...
59,643 views
Why is your LLM slow? Every token, the GPU hauls all the model weights from memory and mostly waits. Speculative decoding ...
137 views
How to clone llama cpp (Step by Step) #how #to #clone #llama #cpp.
1 view
You already run llama.cpp. You might call it Ollama, or LM Studio, or Jan — underneath it is the same engine. On 7 October ...
229 views
llamacpp #localai #localllm Seven free local AI engines claim to beat llama.cpp, sometimes by two, three, or even eight times, but ...
234 views
Join this channel to get access to perks: https://www.youtube.com/channel/@aicodeking/join In this video, I'll test Recursive Flint, ...
18,363 views