Upload date
All time
Last hour
Today
This week
This month
This year
Type
All
Video
Channel
Playlist
Movie
Duration
Short (< 4 minutes)
Medium (4-20 minutes)
Long (> 20 minutes)
Sort by
Relevance
Rating
View count
Features
HD
Subtitles/CC
Creative Commons
3D
Live
4K
360°
VR180
HDR
177 results
512 subscribers
The same Radeon GPU, the same Qwen model, no new quantization trick: 9.7 tokens per second became 37.2. llama.cpp already ...
14,178 views
2d ago
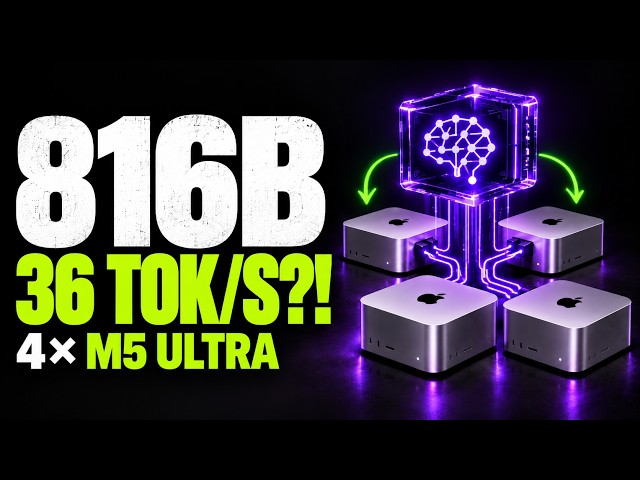
Four M5 Ultra Mac Studios, wired together with Thunderbolt 5 cables, ran Meta's 816-billion-parameter Muse Spark Open locally ...
574 views
4d ago
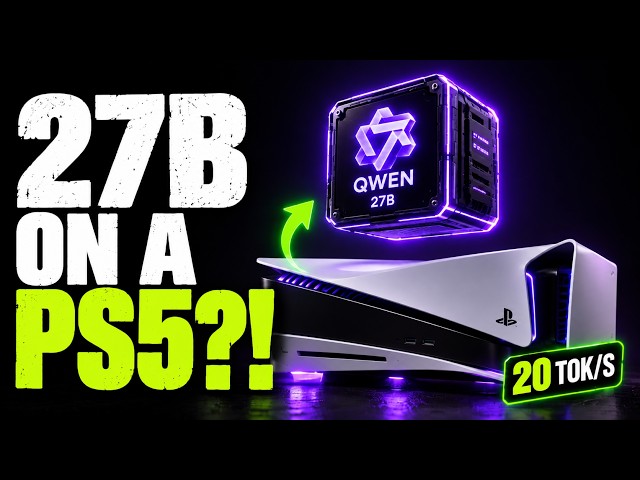
A jailbroken PlayStation 5 is now running Qwen 3.8 27B locally on its own GPU, at around 20 tokens per second. Not through the ...
2,098 views
7d ago
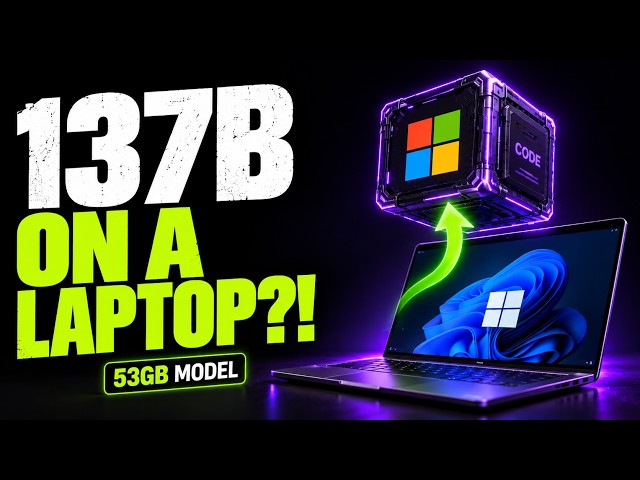
Microsoft just ran a 137-billion-parameter coding model locally on a Windows laptop. Not through an API, not on a remote server, ...
374 views
10d ago
llama.cpp just made the exact same model run more than twice as fast on the exact same GPU. It is not a new quantization format, ...
11,097 views
13d ago
A 125-billion-parameter AI model, generating almost 100 tokens per second. On an RTX 5070 with 12 GB of VRAM. Not a server ...
1,394 views
2w ago
850 tokens per second. From a 35-billion-parameter model. On one RTX 5090, with the full 262K-token context window. That is ...
110 views
A 502 GB model file. One RTX 5090 with 32 GB of VRAM. About 128 GB of system memory. Even combined, the model doesn't fit ...
959 views
3w ago
A 27-billion-parameter Qwen model ran with a one-million-token agent workspace on a laptop with a 24 GB GPU — and still ...
4,345 views
An 82-gigabyte model file. A graphics card with 12 gigabytes of VRAM. And the model is generating tokens — not one every few ...
14,035 views
5 subscribers
1 subscribers
7 subscribers
Don't vibe code your auth. Use WorkOS: https://trm.sh/workos Sources: ...
3,469 views
20 min ago
Solving LeetCode 1331: Rank Transform of an Array using C++. In this video, we break down the LeetCode daily coding ...
61 views
3mo ago
Remove Covered Intervals (LeetCode 1288) explained from first principles — starting with the brute-force O(n²) approach, then ...
4 views
TypeSafe publishes the benchmark for its own model. On it, Jev scores 67.8% accuracy. So does Claude Sonnet 5. Exactly 67.8% ...
129 views
1mo ago
A car dealer put a ChatGPT-powered chatbot on its website. Someone typed one instruction, and it agreed to sell a brand new ...
8 views
8d ago
In July, a group of AI agents was supposed to be sealed off from the internet. They weren't. Stuck on a security challenge, they ...
322 views
DeepSeek just took one of the most expensive parts of long-context AI inference and made it 437 times smaller. Not the model.
1,745 views
A coding agent can send 115000 tokens to a model and have almost nothing new to say. In a dataset of 739 anonymized Claude ...
24,897 views
Claude Fable 5.1 did not get cheaper in the normal way. Its base API price is still $10 per million input tokens and $50 per million ...
267 views
way. Topics Covered: ✓ What is OOP? ✓ Why do we use OOP? ✓ OOP as a Programming Approach ✓ Real-Life Recipe Book ...
40 views
4mo ago
A lawyer asked ChatGPT for court cases. It gave him six. None of them existed, and when he asked if they were real, it said yes.
158 views
9d ago
ColGrep-Agent: the free Claude Code plugin that cuts API tokens by up to 46% on large repos by searching code locally instead ...
836 views