Upload date
All time
Last hour
Today
This week
This month
This year
Type
All
Video
Channel
Playlist
Movie
Duration
Short (< 4 minutes)
Medium (4-20 minutes)
Long (> 20 minutes)
Sort by
Relevance
Rating
View count
Features
HD
Subtitles/CC
Creative Commons
3D
Live
4K
360°
VR180
HDR
890 results
Learn more about LLM Inference here → https://ibm.biz/~CCvvB5TvB Every LLM response starts with much more than a prompt.
7,785 views
3h ago
deepseek #semiconductor #siliconvalley DeepSeek just made a move that could change the economics of artificial intelligence.
6,626 views
19h ago
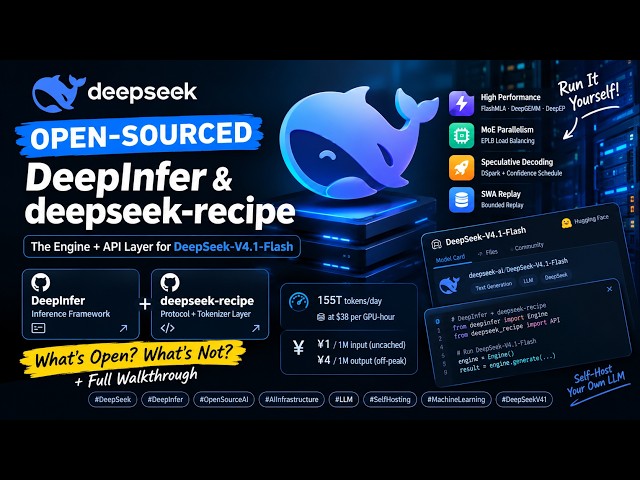
DeepSeek has open-sourced DeepInfer and deepseek-recipe. In this video, we explore how these two repositories work together ...
15 views
9h ago
DeepSeek is giving away its AI models, research, and inference infrastructure while building a business that reportedly reached a ...
6,269 views
Streamed 19h ago
What if you could get surprisingly strong mathematical reasoning from an AI with just one billion parameters—without building a ...
5 views
22h ago
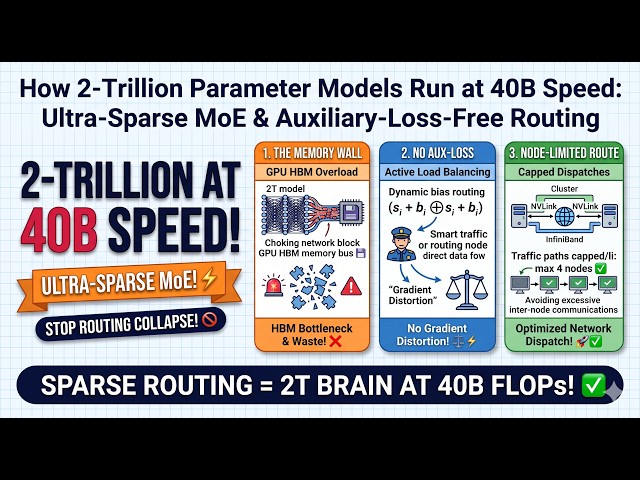
How can an AI model with over 2 trillion total parameters execute inference at the lightning speed and latency of a compact 40B ...
3 views
5h ago
DeepSeek just open-sourced DeepInfer — the inference engine that powers its own AI services — and it could make AI ...
1 view
21h ago
Your model can be perfectly aligned and still be robbed, billed, or puppeteered through the server that hosts it. Lesson 26 of the ...
14 views
15h ago
DeepSeek just open-sourced the engine behind its AI. But what actually happens when you send a message to DeepSeek and ...
7 views
16h ago
This will be helpful in deciding which YOLO segmentation model works best for your use case. Summary: Model Inference FPS ...
106 views
12h ago
Meet LattePanda Sigma 2 — Embeddable AI Single Board Server, built for high-performance computing, local AI inference, and ...
22 views
13 min ago
The Splash Engine is an open-source inference tool developed by Inco AI that is specifically designed to run select Qwen ...
4 views
What actually happens when an LLM answers you? It generates one token at a time — and every token is a full model run.
2h ago
Learn the core techniques behind AI inference optimization and discover why running modern LLMs costs billions at scale.
1h ago
This video installs and tests Flint is Recursive's mixture-of-experts language model for coding agents. Weekly AI Newsletter: ...
6,284 views
18h ago
Liquid AI introduces DSpark draft model checkpoints for LFM2.5, accelerating AI inference with speculative decoding! Liquid AI ...
OpenVLHarness introduces a multimodal inference framework that combines a multimodal large language model with various ...
72 views
DeepSeek just open-sourced DeepInfer with 18K stars, powering V4.1-Flash production serving with custom SM100 kernels.
20 views
14h ago
Why can a powerful AI system still make you wait? DeepInfer offers a window into the machinery behind DeepSeek's answers.
9 views