ViewTube

ViewTube
Sign inSign upSubscriptions
Filters

Upload date

Type

Duration

Sort by

Features

Reset

970,504 results

IBM Technology
AI Inference: The Secret to AI's Superpowers

Download the AI model guide to learn more → https://ibm.biz/BdaJTb Learn more about the technology → https://ibm.biz/BdaJTp ...

10:41
AI Inference: The Secret to AI's Superpowers

177,269 views

1y ago

IBM Technology
What is vLLM? Efficient AI Inference for Large Language Models

Ready to become a certified watsonx AI Assistant Engineer? Register now and use code IBMTechYT20 for 20% off of your exam ...

4:58
What is vLLM? Efficient AI Inference for Large Language Models

111,870 views

1y ago

Caleb Writes Code
Why Inference is hard..

Follow me: X: https://x.com/calebfoundry LinkedIn: https://www.linkedin.com/in/calebeom/ TikTok: ...

15:14
Why Inference is hard..

249,324 views

5mo ago

Caleb Writes Code
Inference Engines explained in 10min..

Try Zapier: https://bit.ly/4yVvOtV Zapier helps you build custom automation and we're looking at how Zapier CLI can help me build ...

10:19
Inference Engines explained in 10min..

76,362 views

2w ago

KodeKloud
AI Training vs Inference Explained

Start Your AI Journey with KodeKloud: https://kode.wiki/4qsrspX AI training and AI inference are two completely different ...

3:30
AI Training vs Inference Explained

10,429 views

3mo ago

New Machina
AI ML Training versus Inference

VIDEO TITLE AI ML Training versus Inference ✍️VIDEO DESCRIPTION ✍️ AI / ML Knowledge one concept at a time.

4:41
AI ML Training versus Inference

14,711 views

2y ago

IBM Technology
Faster LLMs: Accelerate Inference with Speculative Decoding

Ready to become a certified watsonx AI Assistant Engineer? Register now and use code IBMTechYT20 for 20% off of your exam ...

9:39
Faster LLMs: Accelerate Inference with Speculative Decoding

37,567 views

1y ago

PyTorch
Understanding the LLM Inference Workload - Mark Moyou, NVIDIA

Understanding the LLM Inference Workload - Mark Moyou, NVIDIA Understanding how to effectively size a production grade LLM ...

34:14
Understanding the LLM Inference Workload - Mark Moyou, NVIDIA

34,788 views

2y ago

IBM Technology and Red Hat
How KV Cache Speeds Up LLMs for Faster AI Models on GPUs

Learn more about LLM inference here → https://ibm.biz/~Ewjm0UejN Why do LLMs crawl when traffic spikes? Legare Kerrison ...

11:15
How KV Cache Speeds Up LLMs for Faster AI Models on GPUs

207,085 views

3mo ago

AI Engineer
Mastering LLM Inference Optimization From Theory to Cost Effective Deployment: Mark Moyou

LLM inference is not your normal deep learning model deployment nor is it trivial when it comes to managing scale, performance ...

33:39
Mastering LLM Inference Optimization From Theory to Cost Effective Deployment: Mark Moyou

74,770 views

1y ago

AI Engineer
The Small Model Infrastructure Nobody Built (So We Did) — Filip Makraduli, Superlinked

If you're working on small-model inference, embeddings, or GPU infrastructure, this is a practical look at what breaks in the real ...

18:30
The Small Model Infrastructure Nobody Built (So We Did) — Filip Makraduli, Superlinked

35,044 views

5mo ago

Caleb Writes Code
Inference Engines (Part 1)

GTC Sessions: https://www.nvidia.com/gtc/session-catalog/sessions/gtc26-s82448/?ncid=ref-inpa-249-prsp-en-us-1-l33 ...

8:36
Inference Engines (Part 1)

37,706 views

7mo ago

bycloud
The Strange Economics of LLM Inference-as-a-Service

Try out Telnyx and use code BYCLOUD25 for $25 build credits!

23:02
The Strange Economics of LLM Inference-as-a-Service

274,376 views

2w ago

Stanford Online
Stanford CS336 Language Modeling from Scratch | Spring 2026 | Lecture 10: Inference

For more information about Stanford's online Artificial Intelligence programs, visit: https://stanford.io/ai To learn more about ...

1:25:30
Stanford CS336 Language Modeling from Scratch | Spring 2026 | Lecture 10: Inference

16,901 views

5mo ago

NVIDIA
Inference at Scale: The New Frontier for AI Infrastructure and ROI

AI factories are the new industrial engines — and their profitability hinges on how efficiently they generate intelligence. The rise of ...

4:17
Inference at Scale: The New Frontier for AI Infrastructure and ROI

3,073,441 views

1y ago

Y Combinator
Inference, Diffusion, World Models, and More | YC Paper Club

Even if you're a current PhD student, it's hard to keep up with the latest AI research. That's why we started YC Paper Club, a small ...

1:07:19
Inference, Diffusion, World Models, and More | YC Paper Club

147,458 views

4mo ago

IBM Technology
What Is Llama.cpp? The LLM Inference Engine for Local AI

Ready to become a certified watsonx AI Assistant Engineer? Register now and use code IBMTechYT20 for 20% off of your exam ...

9:14
What Is Llama.cpp? The LLM Inference Engine for Local AI

187,110 views

6mo ago

Hugging Face
Inference Providers: Best Way to Build with Open Source Models

Create your account Today https://huggingface.short.gy/join Learn how to call open-source AI models through one consistent ...

18:51
Inference Providers: Best Way to Build with Open Source Models

23,296 views

10mo ago

Steve Brunton
Bayesian Inference: Overview

This video introduces Bayesian inference and statistics, which is a powerful framework for learning distributions from data.

30:16
Bayesian Inference: Overview

67,087 views

8mo ago

AI with Lena Hall
What is AI Inference for Developers | Explained Simply

If you use GPT or Claude, you've probably heard “AI inference” and wondered if you should care. This video explains inference ...

11:52
What is AI Inference for Developers | Explained Simply

58,114 views

11mo ago

Julien Simon
Deep Dive: Optimizing LLM inference

Open-source LLMs are great for conversational applications, but they can be difficult to scale in production and deliver latency ...

36:12
Deep Dive: Optimizing LLM inference

57,086 views

2y ago

CodeEmporium
Causal Inference with Machine Learning - EXPLAINED!

Follow me on M E D I U M: https://towardsdatascience.com/likelihood-probability-and-the-math-you-should-know-9bf66db5241b ...

16:09
Causal Inference with Machine Learning - EXPLAINED!

60,806 views

4y ago

Vizuara
How the VLLM inference engine works?

In this video, we understand how VLLM works. We look at a prompt and understand what exactly happens to the prompt as it ...

1:13:42
How the VLLM inference engine works?

41,724 views

1y ago

PY
The Engineering Behind LLM Inference: The Memory Wall

Challenges and Research Directions for Large Language Model Inference Hardware. https://arxiv.org/abs/2601.05047 - Grattafiori ...

31:13
The Engineering Behind LLM Inference: The Memory Wall

21,170 views

4mo ago

Stanford Online
Stanford CS336 Language Modeling from Scratch | Spring 2025 | Lecture 10: Inference

For more information about Stanford's online Artificial Intelligence programs visit: https://stanford.io/ai To learn more about ...

1:22:52
Stanford CS336 Language Modeling from Scratch | Spring 2025 | Lecture 10: Inference

35,337 views

1y ago

AI Explained in 5 Minutes
Inside LLM Inference: GPUs, KV Cache, and Token Generation

Inside LLM Inference: GPUs, KV Cache, and Token Generation In this deep dive, this video breaks down how Large Language ...

6:56
Inside LLM Inference: GPUs, KV Cache, and Token Generation

2,606 views

9mo ago

NVIDIA Developer
How AI Agents Work: Inside Agentic Inference

What happens when an AI agent starts working, and how do we measure its performance? In this episode of Inside the ...

7:21
How AI Agents Work: Inside Agentic Inference

6,131 views

21h ago

Lightspeed Venture Partners
How vLLM Became the Standard for Fast AI Inference | Simon Mo, Inferact

Inferact CEO and co-founder Simon Mo joins Lightspeed partners Bucky Moore and James Alcorn to break down why inference ...

26:10
How vLLM Became the Standard for Fast AI Inference | Simon Mo, Inferact

1,031,890 views

8mo ago

DataCamp
Understanding LLM Inference | NVIDIA Experts Deconstruct How AI Works

In the last eighteen months, large language models (LLMs) have become commonplace. For many people, simply being able to ...

55:39
Understanding LLM Inference | NVIDIA Experts Deconstruct How AI Works

27,908 views

Streamed 2y ago

AI Engineer
Deep dive on LLM Inference at Scale — Harshul Jain, Audible & Tanmay Sah, Independent AI Researcher

A single token of KV cache on Mistral 7B costs 131 KB. Multiply that by 16000 tokens of context and 80 concurrent users and the ...

1:28:12
Deep dive on LLM Inference at Scale — Harshul Jain, Audible & Tanmay Sah, Independent AI Researcher

12,013 views

1mo ago

Apple Developer
WWDC26: Explore distributed inference and training with MLX | Apple

Learn how to tackle interconnect efficiency, large model inference, request batching, and distributed training challenges. Discover ...

22:07
WWDC26: Explore distributed inference and training with MLX | Apple

54,080 views

4mo ago

Niels Rogge
How a Transformer works at inference vs training time

I made this video to illustrate the difference between how a Transformer is used at inference time (i.e. when generating text) vs.

49:53
How a Transformer works at inference vs training time

72,950 views

3y ago

Think Software
How LLM Inference Works at Scale

Designing AI Inference Systems at Massive Scale ChatGPT now serves 900M+ weekly users and processes trillions of tokens ...

14:53
How LLM Inference Works at Scale

2,367 views

5mo ago

System Overflow - Master System Design Interviews
Batch vs Real-time Inference Explained | Model Serving & Inference | ML System Design

Master the critical decision between batch and real-time inference patterns in production ML systems. Learn when to use each ...

13:46
Batch vs Real-time Inference Explained | Model Serving & Inference | ML System Design

1,831 views

9mo ago

Red Hat
Optimize LLM inference with vLLM

Ready to serve your large language models faster, more efficiently, and at a lower cost? Discover how vLLM, a high-throughput ...

6:13
Optimize LLM inference with vLLM

20,438 views

1y ago

ShowOffer - Tech Interview Coaching Platform
Design Batch Inference System - Anthropic & OpenAI System Design Question

Chapters 0:00 Introduction 4:46 Requirements 7:23 APIs and Entities 10:21 GPU Knowledge 18:34 High Level Design 29:42 ...

52:25
Design Batch Inference System - Anthropic & OpenAI System Design Question

84,948 views

6mo ago

DataMListic
Variational Inference - Explained

In this video, we break down variational inference — a powerful technique in machine learning and statistics — using clear ...

5:35
Variational Inference - Explained

21,177 views

1y ago

ShowOffer - Tech Interview Coaching Platform
How LLM Inference Actually Works

Chapters 0:00 Introduction 4:01 One request, end to end 10:11 Worked example — tokens and the KV grid 15:52 Prefill, decode, ...

40:41
How LLM Inference Actually Works

356,602 views

2mo ago

MIT OpenCourseWare
L14.4 The Bayesian Inference Framework

MIT RES.6-012 Introduction to Probability, Spring 2018 View the complete course: https://ocw.mit.edu/RES-6-012S18 Instructor: ...

9:48
L14.4 The Bayesian Inference Framework

91,713 views

8y ago

Modal
High Performance LLM Inference in Production

The era of actually open AI is here. We've spent the past year helping leading organizations deploy open models and inference ...

1:09:32
High Performance LLM Inference in Production

1,127 views

8mo ago

MIT OpenCourseWare
14. Causal Inference, Part 1

MIT 6.S897 Machine Learning for Healthcare, Spring 2019 Instructor: David Sontag View the complete course: ...

1:18:43
14. Causal Inference, Part 1

196,407 views

5y ago

Hugging Face
Local AI 201: Inference Engines, Hardware Stack

Link to Introduction to Local AI (101) https://www.youtube.com/watch?v=wRcByxXkJCQ - ODS https://github.com/osmantic/ods ...

53:22
Local AI 201: Inference Engines, Hardware Stack

8,818 views

Streamed 2mo ago

Google Cloud
Use Cloud Run for AI Inference

Learn how to run AI inference workloads with GPUs on Cloud Run → https://goo.gle/3ZSSrjr A step-by-step guide on how to ...

5:44
Use Cloud Run for AI Inference

2,805 views

1y ago

AWS Events
AWS re:Invent 2025 - Scaling foundation model inference on Amazon SageMaker AI (AIM424)

Learn how to optimize and deploy popular open-source models like Qwen3, GPT-OSS, and Llama4 using advanced inference ...

53:25
AWS re:Invent 2025 - Scaling foundation model inference on Amazon SageMaker AI (AIM424)

1,279 views

10mo ago

CodeEmporium
Causal Inference - EXPLAINED!

Follow me on M E D I U M: https://towardsdatascience.com/likelihood-probability-and-the-math-you-should-know-9bf66db5241b ...

15:32
Causal Inference - EXPLAINED!

119,355 views

4y ago

Umar Jamil
Attention is all you need (Transformer) - Model explanation (including math), Inference and Training

A complete explanation of all the layers of a Transformer Model: Multi-Head Self-Attention, Positional Encoding, including all the ...

58:04
Attention is all you need (Transformer) - Model explanation (including math), Inference and Training

788,876 views

3y ago

Squintist
AI Chips Are Getting Weird. Here's Why.

Sources & further reading - Patrick O'Shaughnessy — Etched's founders and ambitions: ...

12:41
AI Chips Are Getting Weird. Here's Why.

4,192 views

16h ago

NVIDIA Developer
Introducing NVIDIA Dynamo: Low-Latency Distributed Inference for Scaling Reasoning LLMs

Learn how to deploy and scale reasoning LLMs using NVIDIA Dynamo, a new distributed inference serving framework designed ...

1:29:18
Introducing NVIDIA Dynamo: Low-Latency Distributed Inference for Scaling Reasoning LLMs

14,640 views

1y ago

Amazon Web Services
AI Model Training and Inference on Amazon SageMaker HyperPod EKS | Amazon Web Services

In this Part 1 video, we explore the key challenges of training and deploying large-scale generative AI models — from hardware ...

19:37
AI Model Training and Inference on Amazon SageMaker HyperPod EKS | Amazon Web Services

645 views

7mo ago

Faradawn Yang
LLM Inference Optimization #2: Tensor, Data & Expert Parallelism (TP, DP, EP, MoE)

Part 2 of 5 in the “5 Essential LLM Optimization Techiniques” series. Link to the 5 techiniques roadmap: ...

20:18
LLM Inference Optimization #2: Tensor, Data & Expert Parallelism (TP, DP, EP, MoE)

8,961 views

11mo ago

VLR Software Training
What is AI Inference? | Training vs. Inference Explained

What is AI Inference? | Training vs. Inference Explained #AIInference #TrainingVsInference #MachineLearning #GenerativeAI ...

1:14
What is AI Inference? | Training vs. Inference Explained

2,113 views

10mo ago

IBM Developer and IBM Technology
How to Self-Host an LLM: Local AI Inference with vLLM

Want to try for yourself? Find the code here → https://ibm.biz/~pDRvDsIfj Want to run an LLM on your own hardware? Cedric ...

11:06
How to Self-Host an LLM: Local AI Inference with vLLM

24,608 views

3w ago

SciPy
Hajime Takeda - Introduction to Causal Inference with Machine Learning | SciPy 2024

Causal inference has traditionally been used in fields such as economics, health studies, and social sciences. In recent years ...

30:39
Hajime Takeda - Introduction to Causal Inference with Machine Learning | SciPy 2024

7,551 views

2y ago

Databricks
Scaling Generative AI: Batch Inference Strategies for Foundation Models

Curious how to apply resource-intensive generative AI models across massive datasets without breaking the bank? This session ...

36:10
Scaling Generative AI: Batch Inference Strategies for Foundation Models

681 views

1y ago

Efficient NLP
Quantization vs Pruning vs Distillation: Optimizing NNs for Inference

... https://voicewriter.io Four techniques to optimize the speed of your model's inference process: 0:38 - Quantization 5:59 - Pruning ...

19:46
Quantization vs Pruning vs Distillation: Optimizing NNs for Inference

72,915 views

3y ago

LetsCodeAndAchieve
Training vs Inference | How AI Models Actually Learn

What is the difference between training and inference in Artificial Intelligence? Every AI model goes through two critical stages: ...

5:17
Training vs Inference | How AI Models Actually Learn

626 views

6mo ago

YanAITalk
LLM inference optimization: Architecture, KV cache and Flash attention

... uh and Contin uh continued generated tokens are the responses from the LM from the decoder model and and in this inference ...

44:06
LLM inference optimization: Architecture, KV cache and Flash attention

17,561 views

2y ago

Codemia
How LLM Inference Actually Scales: KV Cache, Batching & vLLM

An LLM serves tokens on $40000 GPUs, and the bottleneck is almost never the math. It is memory and scheduling. This is LLM ...

34:35
How LLM Inference Actually Scales: KV Cache, Batching & vLLM

7,547 views

3mo ago

IBM Technology
What Are Large Reasoning Models (LRMs)? Smarter AI Beyond LLMs

Ready to become a certified watsonx AI Assistant Engineer v1? Register now and use code IBMTechYT20 for 20% off of your ...

8:38
What Are Large Reasoning Models (LRMs)? Smarter AI Beyond LLMs

162,155 views

11mo ago

GrammarSongs by Melissa
Inferences | Making Inferences | Award Winning Inferences Teaching Video | What is an inference?

Making Inferences |This video explains the method in which good readers combine clues found in the text with prior knowledge to ...

6:08
Inferences | Making Inferences | Award Winning Inferences Teaching Video | What is an inference?

1,599,526 views

6y ago

Jonathan.Interviews
Data science tutorial: Synthetic Control Models for Causal Inference

Synthetic Control Method - Data Science Tutorial! Data scientists: ever wonder how to measure TRUE treatment effects when you ...

5:15
Data science tutorial: Synthetic Control Models for Causal Inference

2,821 views

1y ago

No Priors: AI, Machine Learning, Tech, & Startups
Why Diffusion Will Win AI Inference with Inception Co-Founder and CEO Stefano Ermon

As generative AI hits hardware and latency bottlenecks, Stanford professor, diffusion pioneer, and Inception co-founder and CEO ...

38:14
Why Diffusion Will Win AI Inference with Inception Co-Founder and CEO Stefano Ermon

11,488 views

3w ago

CNCF [Cloud Native Computing Foundation]
Project Lightning Talk: Evolving KServe: The Unified Model Inference Platform For Both... Yuan Tang

Don't miss out! Join us at our next KubeCon + CloudNativeCon events in Mumbai, India (18-19 June, 2026), Yokohama, Japan ...

4:53
Project Lightning Talk: Evolving KServe: The Unified Model Inference Platform For Both... Yuan Tang

520 views

6mo ago

Google for Developers
How do thinking and reasoning models work?

LLMs that can "think" and "reason" have become increasingly popular. But what is a model actually doing when it's "thinking" and ...

13:26
How do thinking and reasoning models work?

51,866 views

10mo ago

Momento
Should You Self-Host Inference? • Daniel Svonava • Infer Summit 2026

This session was recorded at the Infer Summit 2026. Daniel Svonava, CEO of Superlinked, argues for self-hosting smaller ...

32:48
Should You Self-Host Inference? • Daniel Svonava • Infer Summit 2026

58 views

2mo ago

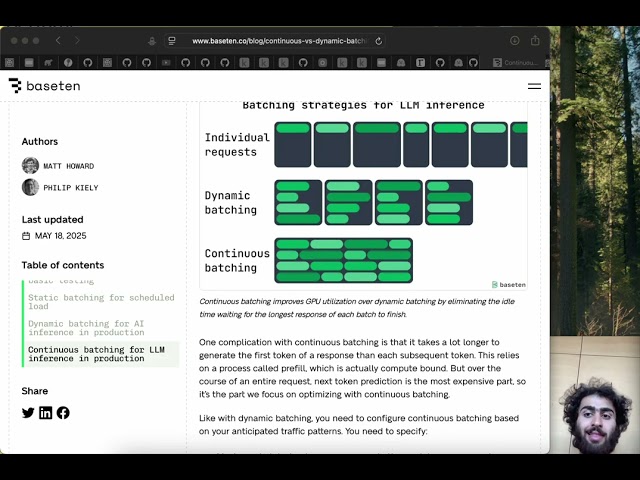
neuralkian
Gentle Introduction to Static, Dynamic, and Continuous Batching for LLM Inference

https://www.baseten.co/blog/continuous-vs-dynamic-batching-for-ai-inference/#continuous-batching-for-llm-inference-in- ...

7:34
Gentle Introduction to Static, Dynamic, and Continuous Batching for LLM Inference

2,897 views

1y ago

InfraWithSimblex
What Happens When You Ask AI a Question? | LLM Inference Explained

What happens between sending an AI a question and seeing its answer? This beginner-friendly visual guide follows a prompt ...

7:46
What Happens When You Ask AI a Question? | LLM Inference Explained

20 views

10d ago

Kai
New Local AI Inference Engine You Should Be Using in 2027 ? (FreeToken)

Can a 753-billion parameter open-source AI model really run on a single desktop GPU with only 96GB of VRAM and still produce ...

16:17
New Local AI Inference Engine You Should Be Using in 2027 ? (FreeToken)

39,063 views

1mo ago

Abdul Jabbar
AI Infrastructure (GPUs,vLLM,LLM-D & KV Cache) | AI Inference Stack Explained

How AI Inference Works: From Prompt to Response In this video, I break down the complete LLM inference architecture and what ...

23:25
AI Infrastructure (GPUs,vLLM,LLM-D & KV Cache) | AI Inference Stack Explained

772 views

2w ago

Why This in Tech?
Why AI Inference is a Memory Bandwidth Problem

Discover why the bottleneck in modern AI isn't raw compute power, but the speed of data movement. We explore the 'Memory ...

6:16
Why AI Inference is a Memory Bandwidth Problem

685 views

5mo ago

Joe Maddalone
Splash AI on Mac: 5x Faster vs OMLX

Boost your local AI workflow with Splash AI's cutting-edge inference engine, delivering up to five times faster performance than ...

4:52
Splash AI on Mac: 5x Faster vs OMLX

16,244 views

13d ago

Mike Jonas Econometrics
Causal Inference: A Simple Difference-in-Difference Model

An explanation and data example of a simple Difference-in-Difference model, with an example in Stata. Link to excellent new ...

26:38
Causal Inference: A Simple Difference-in-Difference Model

75,004 views

5y ago

AI deepdive
LLM Inference Optimization Explained — From 8 Tokens/sec to 50+

Why does a 70B language model crawl at 8 tokens per second on one setup, then feel instant on another? The difference is ...

10:14
LLM Inference Optimization Explained — From 8 Tokens/sec to 50+

297 views

4mo ago

AI Research Roundup
DFlash: Faster LLM Inference via Block Diffusion

In this AI Research Roundup episode, Alex discusses the paper: 'DFlash: Block Diffusion for Flash Speculative Decoding' DFlash ...

4:39
DFlash: Faster LLM Inference via Block Diffusion

586 views

8mo ago

Liquid AI
Why LLM Inference Is Memory-Bound, Not Compute-Bound

The limiting factor in LLM inference isn't compute. It's how fast you can move weights from DRAM to the chip. In this interview, CTO ...

4:48
Why LLM Inference Is Memory-Bound, Not Compute-Bound

655 views

4mo ago

Practical stats
Causal Inference Intuition: Difference-in-Differences Explained Simply

"Correlation is not causation." We hear it all the time, but how do we actually prove an effect? In this deep dive, we explore ...

3:26
Causal Inference Intuition: Difference-in-Differences Explained Simply

1,173 views

7mo ago

Show more