Upload date
All time
Last hour
Today
This week
This month
This year
Type
All
Video
Channel
Playlist
Movie
Duration
Short (< 4 minutes)
Medium (4-20 minutes)
Long (> 20 minutes)
Sort by
Relevance
Rating
View count
Features
HD
Subtitles/CC
Creative Commons
3D
Live
4K
360°
VR180
HDR
2,243,837 results
A person on Reddit asked those who spent more than $10000 on a local AI setup whether they regret it. Meanwhile a used RTX ...
10,979 views
4 days ago
Looking for the best GPU for your Local AI setup, LLM inference, or fine-tuning without overspending? In this video, we break ...
83,608 views
5 days ago
Try out Hybrid Compute: https://samuelgregory.co.uk/perplexity The era of sending every single byte of your sensitive data to a ...
14,139 views
6 days ago
Intel Arc B580 ($250, 12GB) runs local AI surprisingly fast. See real token/sec benchmarks, OpenVINO vs SYCL setup, and ...
5,947 views
7 hours ago
Buy one on Amazon: https://lon.tv/291nh - also find the aaostar dock here: https://amzn.to/3TcsM5b (compensated affiliate links).
281,312 views
2 weeks ago
For years the rule was simple: serious local AI needs 24GB or more. This video breaks that rule. A new non-uniform GGUF ...
394,811 views
8 days ago
What is the best local AI hardware for your budget—and how much memory do you actually need to run today's largest local LLMs ...
9,533 views
9 days ago
... mixture of experts architecture with 100 routed experts per layer, which changes how you need to think about local AI hardware.
395,437 views
A $780 graphics card can leave less room for your coding model than an older mac mini. Your $1000 budget needs to buy the ...
2,151 views
2 days ago
An RTX 5090 and a 64GB mac mini share an impressive local AI shortlist. Change the model, the task, or the used hardware deal, ...
9,573 views
17 hours ago
What is the cheapest, and most valuable, way to reach 48GB of memory for local AI in 2026? In this video, I compare nearly every ...
901 views
2 hours ago
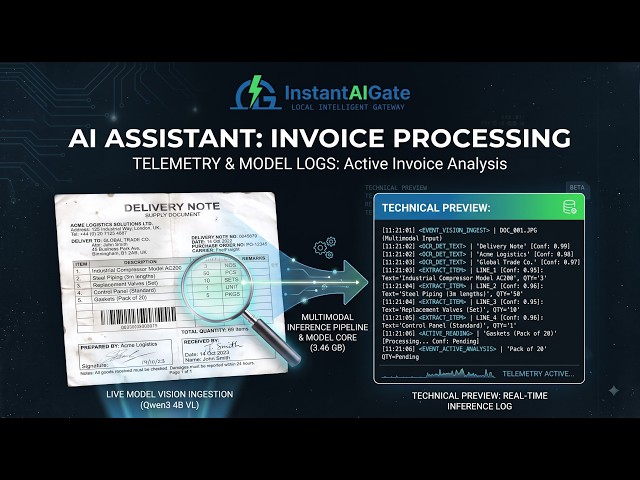
Deploy secure, edge-ready AI. Our system utilizes a highly optimized 3.46 GB local Vision Language Model (Qwen3 4B VL), ...
41 views
1 month ago
Spark-X2.5-4B is a compact 4-billion parameter model configured with a native 1048576-token context window. While fitting a 4B ...
22,656 views
Locally controlled, non-cloud based computer vision for your security cameras. Thanks to PCBWay (https://www.pcbway.com) for ...
581,962 views
6 years ago
I learned a TON on this trip about local AI models, hardware and less traditional models like Aurora. A huge thank you to Logitech ...
12,704 views
2 months ago
We evaluate inference speed (~68–70 tokens/sec) of Ternary Bonsai 2 27B and put its agentic coding capabilities to the test with ...
81,228 views
Subscribe to RepoChad for more local AI hardware guides, model breakdowns, and real-world inference comparisons.This video ...
112,312 views
... 09:25 AMD's Software Advantage 10:02 What a Serious Local AI Workflow Looks Like 12:27 The Problem With Cheap Ryzen AI ...
41,806 views
If your own PC doesn't have a powerful GPU, this method can be useful for experimenting with larger local AI models without ...
72,608 views
In the age of AI, data security is paramount. The choice between processing data on remote cloud servers or on local hardware ...
19 views
1 year ago
Show more