Upload date
All time
Last hour
Today
This week
This month
This year
Type
All
Video
Channel
Playlist
Movie
Duration
Short (< 4 minutes)
Medium (4-20 minutes)
Long (> 20 minutes)
Sort by
Relevance
Rating
View count
Features
HD
Subtitles/CC
Creative Commons
3D
Live
4K
360°
VR180
HDR
11,894 results
What local AI models can you run on a regular computer, without a powerful desktop GPU? I ran six LLMs, from 5B to 35B ...
71,866 views
6d ago
Dip your toe into local AI at Micro Center, the AI destination: https://micro.center/322535 Austin, Texas: sign up now for a FREE ...
28,630 views
3h ago
Supported systems can allocate up to 160GB as graphics memory, creating more room for large local AI models and longer ...
13,077 views
5d ago
A person on Reddit asked those who spent more than $10000 on a local AI setup whether they regret it. Meanwhile a used RTX ...
11,456 views
Intel Arc B580 ($250, 12GB) runs local AI surprisingly fast. See real token/sec benchmarks, OpenVINO vs SYCL setup, and ...
15,859 views
2d ago
Looking for the best GPU for your Local AI setup, LLM inference, or fine-tuning without overspending? In this video, we break ...
91,216 views
7d ago
The open versions of Jev are here . In this video we go through 7 of the open Jev style models to see how good they are and what ...
162,294 views
3d ago
M5 Ultra Mac Studio local AI speed, measured: tokens per second and prompt processing on Qwen 3.8 27B, against the M3 Ultra, ...
14,652 views
23h ago
What is the cheapest, and most valuable, way to reach 48GB of memory for local AI in 2026? In this video, I compare nearly every ...
20,532 views
Bosgame M5 mini PC with 128GB unified memory: can a $2999 local AI desktop actually run 120B models faster than an RTX ...
13,438 views
1d ago
Want to try for yourself? Find the code here → https://ibm.biz/~pDRvDsIfj Want to run an LLM on your own hardware? Cedric ...
10,712 views
Everyone knows an ordinary computer can load a small AI model today. But loading a model into memory is the easy part.
12,580 views
A $780 graphics card can leave less room for your coding model than an older mac mini. Your $1000 budget needs to buy the ...
2,348 views
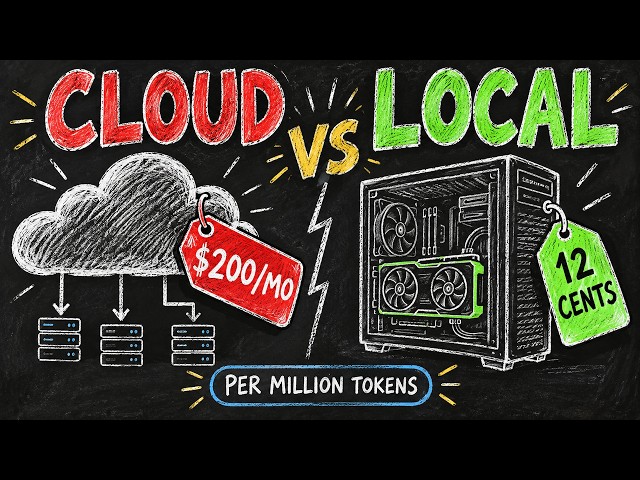
A $200 a month AI subscription is $2400 a year. Running a model on your own GPU costs between 6 and 38 cents per million ...
9 views
If your own PC doesn't have a powerful GPU, this method can be useful for experimenting with larger local AI models without ...
88,878 views
RTX 5090 local AI inference just got up to 1.9× faster according to NVIDIA, thanks to new llama.cpp optimizations. But does that ...
1,051 views
We evaluate inference speed (~68–70 tokens/sec) of Ternary Bonsai 2 27B and put its agentic coding capabilities to the test with ...
93,007 views
Spark-X2.5-4B is a compact 4-billion parameter model configured with a native 1048576-token context window. While fitting a 4B ...
23,024 views
In this one, I set up a fully local, self-hosted LLM on my PC using Ollama — no cloud, no API calls, no data leaving my machine.
39 views
4d ago
The first time you run a large language model on your own computer, it will be worse than the free one in your browser. It will be ...
2,051 views
Show more