Upload date
All time
Last hour
Today
This week
This month
This year
Type
All
Video
Channel
Playlist
Movie
Duration
Short (< 4 minutes)
Medium (4-20 minutes)
Long (> 20 minutes)
Sort by
Relevance
Rating
View count
Features
HD
Subtitles/CC
Creative Commons
3D
Live
4K
360°
VR180
HDR
19 results
Four M5 Ultra Mac Studios, wired together with Thunderbolt 5 cables, ran Meta's 816-billion-parameter Muse Spark Open locally ...
608 views
6d ago
Microsoft just ran a 137-billion-parameter coding model locally on a Windows laptop. Not through an API, not on a remote server, ...
378 views
11d ago
The same Radeon GPU, the same Qwen model, no new quantization trick: 9.7 tokens per second became 37.2. llama.cpp already ...
15,809 views
3d ago
A car dealer put a ChatGPT-powered chatbot on its website. Someone typed one instruction, and it agreed to sell a brand new ...
9 views
9d ago
850 tokens per second. From a 35-billion-parameter model. On one RTX 5090, with the full 262K-token context window. That is ...
112 views
3w ago
A lawyer asked ChatGPT for court cases. It gave him six. None of them existed, and when he asked if they were real, it said yes.
158 views
10d ago
A 125-billion-parameter AI model, generating almost 100 tokens per second. On an RTX 5070 with 12 GB of VRAM. Not a server ...
1,399 views
2w ago
A jailbroken PlayStation 5 is now running Qwen 3.8 27B locally on its own GPU, at around 20 tokens per second. Not through the ...
2,147 views
8d ago
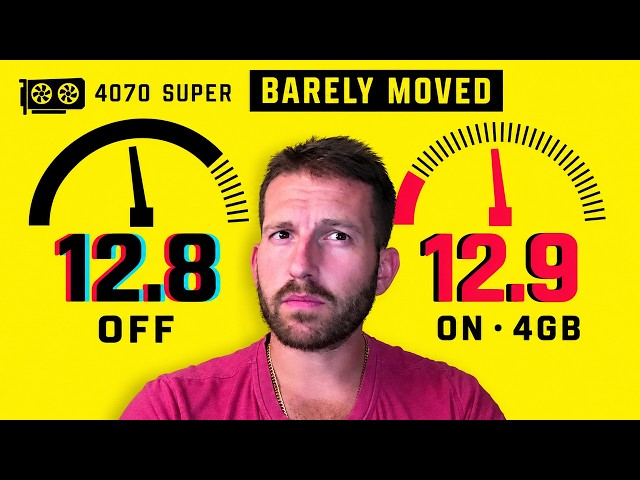
Strata vs llama.cpp's new expert cache on a 12GB RTX 4070 SUPER with 32GB of RAM. Same Qwen 3.8 Flash Next Coder file, ...
3,883 views
A 27-billion-parameter Qwen model ran with a one-million-token agent workspace on a laptop with a 24 GB GPU — and still ...
4,347 views
llama.cpp just made the exact same model run more than twice as fast on the exact same GPU. It is not a new quantization format, ...
11,125 views
A 502 GB model file. One RTX 5090 with 32 GB of VRAM. About 128 GB of system memory. Even combined, the model doesn't fit ...
959 views
In this video, I showcase a custom Python script that successfully *decrypts a `.pye` file* protected by SourceDefender 16.x.
154 views
An 82-gigabyte model file. A graphics card with 12 gigabytes of VRAM. And the model is generating tokens — not one every few ...
14,040 views
4w ago
Welcome back to Eh?!? OOP! In Episode 3, we are having a real, unfiltered conversation about respect, boundaries, and the ...
62 views
7d ago