ViewTube

ViewTube
Sign inSign upSubscriptions
Filters

Upload date

Type

Duration

Sort by

Features

Reset

26,116 results

That DevOps Guy
Run AI Models Locally with llama.cpp

Follow the DevOps roadmap https://www.instagram.com/marceldempers My DevOps Roadmap ...

22:41
Run AI Models Locally with llama.cpp

36,616 views

5mo ago

Kai
llama.cpp Just Made 125B MoE Models 4× Faster!

llama.cpp's new MoE expert cache took a 125B model from 9.7 to 37.2 tokens a second on one 24 GB GPU. Here's where that 4× ...

28:32
llama.cpp Just Made 125B MoE Models 4× Faster!

52,217 views

2d ago

pookie
How to Run Local LLMs with Llama.cpp: Complete Guide

In this guide, you'll learn how to run local llm models using llama.cpp. In this llamacpp guide you will learn everything from model ...

1:07:19
How to Run Local LLMs with Llama.cpp: Complete Guide

35,490 views

1y ago

SchizoDev
STOP. You're Installing Local AI Right Now (Llama.cpp)

Man yells at cloud and suggests you do the same. 00:00 - Intro 06:18 - Inference engine 09:50 - Quick start 12:56 - Basic settings ...

1:18:36
STOP. You're Installing Local AI Right Now (Llama.cpp)

301,142 views

2mo ago

Tonbi's AI Garage
The Best Way to Take Control of Your Local AI Model (llama.cpp)

Ollama, LM Studio, Jan — they're all just wrappers around one engine: llama.cpp. Here's how to run it directly and take real ...

24:22
The Best Way to Take Control of Your Local AI Model (llama.cpp)

22,611 views

4mo ago

Bijan Bowen
Llama.cpp OFFICIAL WebUI - First Look & Windows 11 Install Guide!

Timestamps: 00:00 - Intro 01:04 - llamacpp Overview 02:39 - llamacpp Install 05:47 - System Hardware Disclaimer 06:37 ...

22:23
Llama.cpp OFFICIAL WebUI - First Look & Windows 11 Install Guide!

33,008 views

11mo ago

Lukasz Gawenda
Qwen3.8 Flash: Over 7x Faster First Token | llama.cpp vs SGLang vs FreeToken. Benchmarked!

Qwen3.8-Flash-Next: 35.4 seconds to the first token in SGLang versus 258.4 in llama.cpp. A 7.3x gap on the same GPU in my ...

43:52
Qwen3.8 Flash: Over 7x Faster First Token | llama.cpp vs SGLang vs FreeToken. Benchmarked!

8,956 views

1mo ago

YourAvgDev
Building llama cpp for CPU LLM inference in 2026.

Refreshing my llama.cpp build tutorial. This is a guide for computers without any GPUs. The goal is to demonstrate that it isn't ...

33:31
Building llama cpp for CPU LLM inference in 2026.

629 views

1mo ago

Country Boy Computers
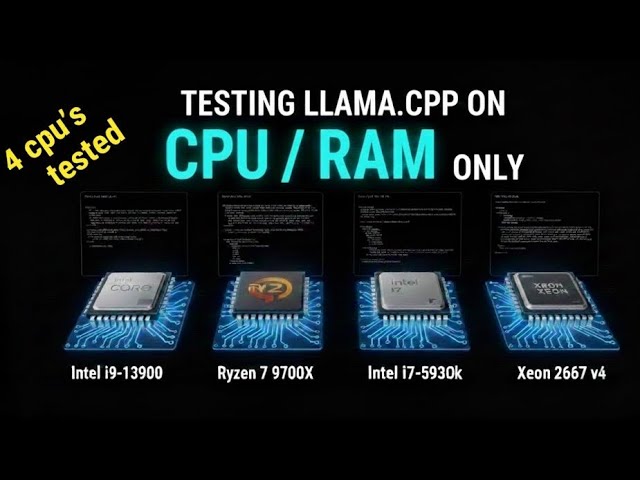
LLAMA.CPP CPU/RAM Showdown: i9-13900 vs Ryzen 7 9700X vs i7-5930K vs Xeon E5 2667 | GPT-OSS:20b

"If you buy sumthin' through these links, this ol' boy might snag a small commission—enough to buy a biscuit—at no extra cost to ...

36:03
LLAMA.CPP CPU/RAM Showdown: i9-13900 vs Ryzen 7 9700X vs i7-5930K vs Xeon E5 2667 | GPT-OSS:20b

13,937 views

10mo ago

YourAvgDev
Building llama.cpp for NVIDIA GPU LLM Inference in 2026

It is pretty easy to get basic CUDA support enabled for llama.cpp. It requires an NVIDIA GPU and just reconfiguring the cmake ...

32:04
Building llama.cpp for NVIDIA GPU LLM Inference in 2026

870 views

3w ago

Codacus
Colibrì vs llama.cpp: Running DeepSeek V4 284B on CPU

Run 360GB models on 8GB RAM using Colibri technology. This approach challenges NVIDIA dominance in local LLM inference.

23:48
Colibrì vs llama.cpp: Running DeepSeek V4 284B on CPU

167,570 views

2mo ago

Codacus
Can You Run Any LLM in Jev Mode Using llama.cpp?

Jev answers in milliseconds, picks from your options instead of writing a paragraph, and you need a waitlist spot to try it. I added ...

26:50
Can You Run Any LLM in Jev Mode Using llama.cpp?

92,647 views

1mo ago

Probably Private
Serving AI Locally: Introduction to llama.cpp

Interested in serving AI models locally for your own use and to check out new models? This video is an introduction to llama.cpp, ...

21:41
Serving AI Locally: Introduction to llama.cpp

1,620 views

6mo ago

Lukasz Gawenda
Fastest Qwen 3.8 27B in Llama.cpp? DFlash 2 + n-gram Explained & Benchmarked!

DFlash 2 + n-gram speculative decoding in llama.cpp took Qwen 3.8 27B from 65 to 305 tok/s (4.68x) on a real multi-turn coding ...

48:49
Fastest Qwen 3.8 27B in Llama.cpp? DFlash 2 + n-gram Explained & Benchmarked!

21,085 views

2mo ago

Digital Spaceport
Local Ai Server Setup Guides Proxmox 9 - Llama.cpp in LXC w/ GPU Passthrough

In this Local Ai setup guide I show you how to build llama.cpp in an LXC with quad 3090s, download LLMs from unsloth hosted off ...

22:36
Local Ai Server Setup Guides Proxmox 9 - Llama.cpp in LXC w/ GPU Passthrough

23,311 views

1y ago

Julien Simon
Run SLMs locally: Llama.cpp vs. MLX with 10B and 32B Arcee models

In this video, we run local inference on an Apple M3 MacBook with llama.cpp and MLX, two projects that optimize and accelerate ...

20:34
Run SLMs locally: Llama.cpp vs. MLX with 10B and 32B Arcee models

33,707 views

1y ago

Jarods Journey
Tutorial: Local AI Agent with llamacpp and OpenCode on Windows

Links referenced in the video: node - https://nodejs.org/en/download git - https://git-scm.com/install/windows uv ...

28:25
Tutorial: Local AI Agent with llamacpp and OpenCode on Windows

5,566 views

4mo ago

Byte Goose AI.
The Architecture of Llama.cpp: Foundations and Acceleration. Porsche 911 GT3 RS Inference Beast.

The Architecture of Llama.cpp: Foundations and Acceleration The podcast provides a comprehensive overview of the ggml ...

1:03:02
The Architecture of Llama.cpp: Foundations and Acceleration. Porsche 911 GT3 RS Inference Beast.

580 views

1y ago

Country Boy Computers
Dual Instinct Mi50-32gb llama.cpp | gpt-oss:120b qwen3:30b gpt-oss:20b MoE bliss in home LLM

"If you buy sumthin' through these links, this ol' boy might snag a small commission—enough to buy a biscuit—at no extra cost to ...

21:18
Dual Instinct Mi50-32gb llama.cpp | gpt-oss:120b qwen3:30b gpt-oss:20b MoE bliss in home LLM

14,775 views

11mo ago

WASM I/O
P2P Distributed LLM Inference Across Browsers With llama.cpp And WebRTC by Kohei Tokunaga @ Wasm I/O

Wasm I/O 2026 - Barcelona, 19-20 March Slides: ...

29:38
P2P Distributed LLM Inference Across Browsers With llama.cpp And WebRTC by Kohei Tokunaga @ Wasm I/O

1,168 views

2mo ago